DevOps & CI/CD Foundations
Continuous integration, continuous delivery, release flow, environments, automation and team responsibilities.
Equip your data engineering teams with practical CI/CD skills to version, validate, test, build and deploy SQL, Python, ETL and data-pipeline workloads through repeatable engineering workflows.
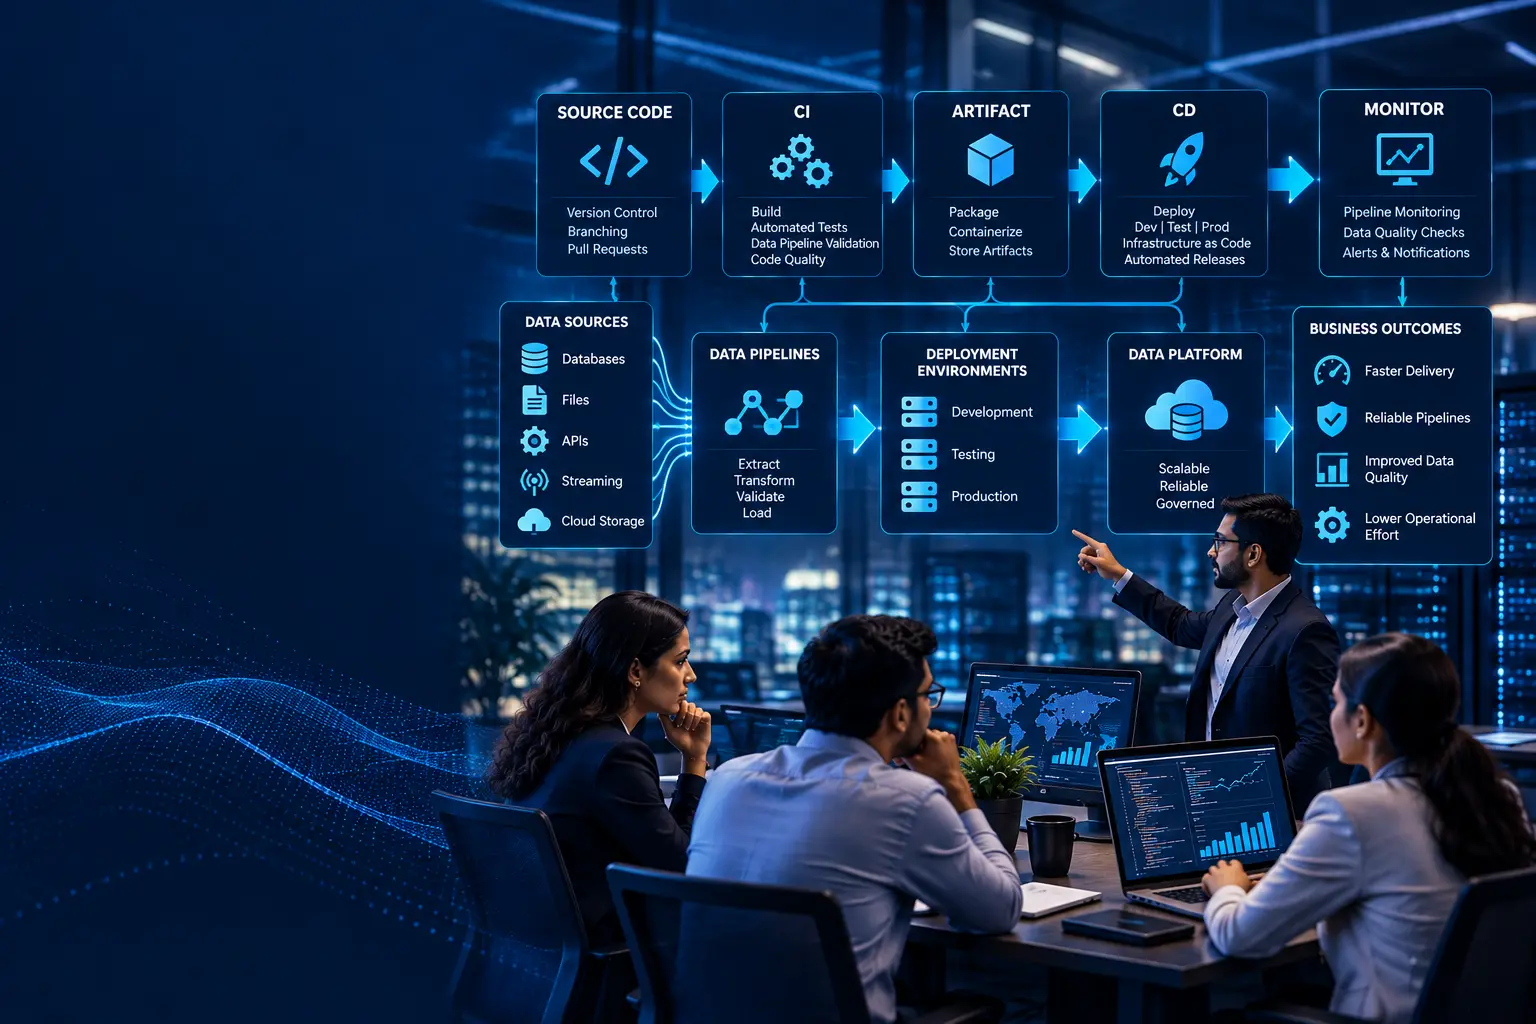
Modern data teams need more than source control. They need repeatable ways to validate changes, package pipeline components, promote releases across environments, protect configuration, recover from failed deployments and monitor production workloads.
Corporate CI/CD training from Crystalspiders connects DevOps engineering practices with practical data workloads such as ETL packages, SQL scripts, Python applications, pipeline definitions, orchestration code and data-quality checks.
The program can be aligned to your current repositories, branching standards, test strategy, deployment architecture and data platform so teams can apply the practices directly to day-to-day delivery.
Practical modules can be adjusted for your team's engineering maturity, delivery model and technology stack.
Continuous integration, continuous delivery, release flow, environments, automation and team responsibilities.
Repositories, commits, branches, merges, pull requests, code review and collaboration workflows.
Feature branches, release branches, trunk-based approaches and controlled promotion patterns.
Automated builds, linting, code checks, SQL/Python validation and pipeline compilation or packaging.
Unit, integration, schema, data-quality, reconciliation and deployment-readiness checks.
Versioned deployment packages, build outputs, dependencies, containers and artifact repositories.
Automated promotion through development, test, staging and production environments with controls.
Environment-specific settings, credentials, secure variables and configuration management practices.
Safe releases, approvals, rollback planning, blue-green or canary concepts and change management.
Introduction to automating infrastructure and platform configuration where it supports repeatable data delivery.
Deployment status, pipeline health, failures, data-quality signals, logs and operational feedback.
Approvals, traceability, auditability, standards and controlled production delivery.
Create traceable changes in Git with a consistent collaboration workflow.
Run automated code, SQL, Python, package and pipeline validation checks.
Execute data-pipeline tests and create versioned deployment artifacts.
Move approved releases across controlled environments with repeatable automation.
Track pipeline behavior, failures and data quality, then feed lessons back into delivery.
Examples can be selected according to the tools already used by your organization.
Source control, branching and collaboration workflows.
Repository-driven automation and release workflows.
Integrated build, test and deployment pipelines.
Flexible automation for enterprise CI/CD scenarios.
Repos, pipelines and release management for Microsoft environments.
Version-controlled data transformation and engineering code.
Deployable pipeline logic, transformations and data-quality checks.
Environment-aware delivery for modern data platforms.
For teams building and maintaining production data pipelines.
For developers moving ETL and transformation changes through environments.
For teams operating shared data platforms and deployment automation.
For practitioners extending CI/CD patterns into data workloads.
For leaders standardizing engineering workflows across data teams.
For architects defining scalable, governed data delivery processes.
CI/CD Pipelines for Data Engineering training helps organizations apply software engineering delivery practices to SQL, Python, ETL, ELT and analytics engineering workloads. The focus is on repeatable source-control, validation, build, deployment and monitoring workflows that support reliable data-pipeline delivery.
The program can cover Git repositories, pull requests, branching strategies, automated testing, data-quality checks, build automation, package and artifact management, environment-specific configuration, release approvals, deployment automation, rollback procedures and post-deployment monitoring. Depending on the organization's technology stack, examples can be adapted to GitHub Actions, GitLab CI/CD, Jenkins, Azure DevOps or other established CI/CD platforms.
For data engineering teams, CI/CD can connect application-style engineering discipline with practical pipeline concerns: schema changes, SQL transformations, Python code, ETL packages, orchestration definitions, configuration and data validation. This makes the training relevant to teams working with data warehouses, data lakes, lakehouse platforms, cloud services and enterprise analytics environments.
Corporate delivery can be customized for developers, data engineers, DevOps teams, platform engineers, technical leads and architects. Project-oriented exercises can demonstrate how a change moves from version control through automated checks, packaging and controlled deployment into an observable production data workflow.
Common questions about corporate CI/CD and data engineering delivery programs.
This corporate training explains how to apply continuous integration and continuous delivery practices to data engineering work. Teams learn source control, branching, automated validation, data pipeline testing, artifact management, deployment workflows, environment promotion, rollback and operational monitoring.
The program is suitable for data engineers, ETL developers, data platform engineers, analytics engineers, DevOps engineers, software engineers working on data pipelines, technical leads and architects who need repeatable delivery practices for data workloads.
Yes. The curriculum can cover Git fundamentals, repositories, commits, pull requests, branching models, merge practices, code review and team collaboration patterns used to manage ETL, Python, SQL and pipeline configuration changes.
Yes. The training addresses practical validation for data engineering, including code quality checks, unit and integration tests, schema validation, data-quality checks, configuration validation and pipeline-level verification before deployment.
Delivery can be tailored around the technology stack used by your organization, including platforms such as GitHub Actions, GitLab CI/CD, Jenkins and Azure DevOps, together with the organization's repository, build, deployment and environment-management practices.
Yes. Corporate sessions can use relevant examples from your organization's ETL, Python, SQL, cloud, data warehouse, data lake or orchestration environment while keeping confidential business information protected.
Discuss your current repositories, CI/CD platform, data stack, project requirements and preferred delivery format with Crystalspiders.