Lakehouse Architecture
Understand lakehouse concepts, medallion architecture, storage patterns and practical design approaches for modern data platforms.
Upskill data engineering, analytics and technology teams with practical Databricks training covering lakehouse architecture, Apache Spark, Delta Lake, Databricks SQL, Lakeflow, Unity Catalog and production-focused data workflows.
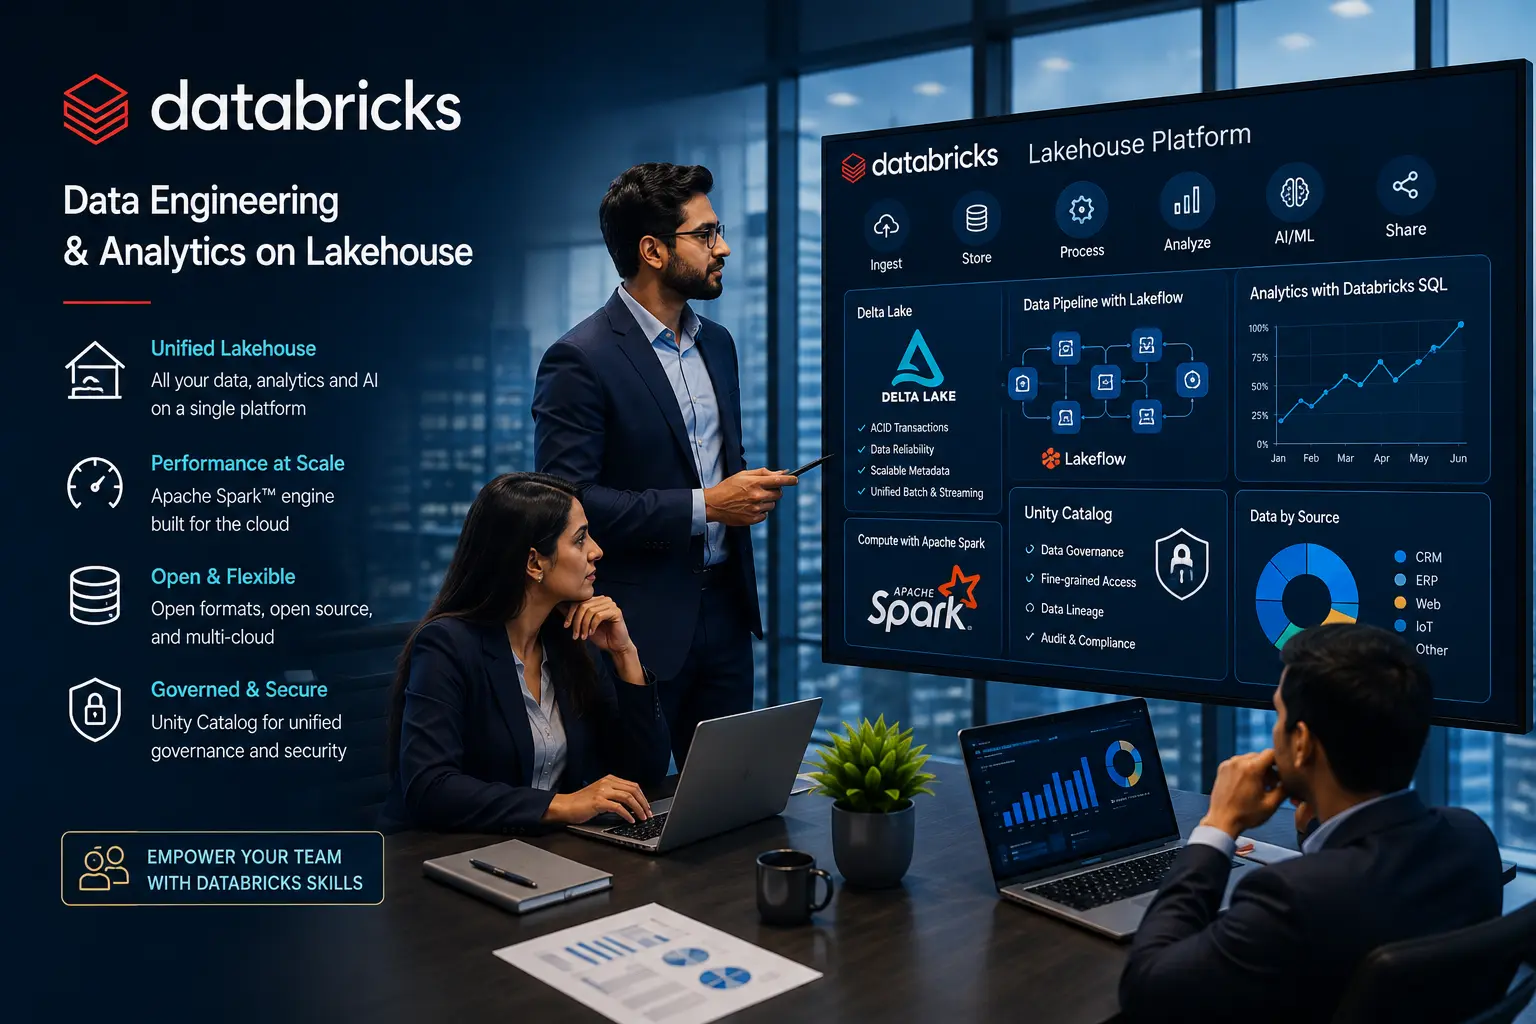
Modern data architecture
Scalable data processing
Reliable data pipelines
Governance and lineage
SQL and BI workloads
Build practical capability across data engineering, analytics, governance and production data workflows in a unified environment.
Understand lakehouse concepts, medallion architecture, storage patterns and practical design approaches for modern data platforms.
Work with notebooks, Spark DataFrames, transformations, joins, aggregations and scalable batch processing techniques.
Build repeatable ingestion and transformation workflows and understand scheduling, orchestration and production execution patterns.
Develop reliable tables and pipelines using Delta Lake concepts such as ACID transactions, schema evolution and incremental processing.
Query lakehouse data, work with SQL warehouses and develop dashboards and analytics workflows for business-facing teams.
Apply Unity Catalog concepts for access control, discovery, auditing, governance and lineage across governed data assets.
The curriculum can be customized for data engineers, analysts, developers, architects and technical teams based on project requirements.
A structured corporate learning model designed around your team's technology stack, projects and business objectives.
Identify roles, skill levels, projects and expected outcomes.
Map the training to your Databricks and data platform requirements.
Practice notebooks, pipelines, SQL and engineering scenarios.
Evaluate practical skills and identify the next development areas.
Databricks brings together data engineering, analytics and lakehouse workloads in a unified data platform. Teams need practical skills to work with Apache Spark, Delta Lake, data pipelines, SQL workloads and governed data assets.
Crystalspiders provides corporate Databricks training for data engineers, analysts, developers, architects and technology teams. Programs can cover lakehouse architecture, Apache Spark, Delta Lake, Lakeflow, Databricks SQL, Unity Catalog, production workflows and modern data engineering practices.
Teams can build a practical understanding of lakehouse architecture, medallion-style data organization, storage patterns and platform workflows. Training can be aligned with the architecture and operating model used within your organization's data platform.
Corporate Databricks programs can include Apache Spark DataFrames, transformations, joins, aggregations and scalable batch-processing concepts. Hands-on exercises can be designed around the data volumes, pipelines and workloads relevant to your engineering teams.
Teams can work with Delta Lake concepts including reliable tables, transactional processing, schema evolution and incremental data workflows. Training can also include pipeline development, orchestration, scheduling, monitoring and production-oriented operational practices.
Databricks training can include SQL queries, SQL warehouses, analytics-ready data models, dashboards and reporting workflows for business-facing teams. The curriculum can connect engineering practices with practical analytics requirements.
Governed data platforms require consistent access and discovery practices. Training can include Unity Catalog concepts such as catalogs, schemas, permissions, auditing, discovery and lineage across governed data assets.
Training can be customized around your team's roles, experience levels, Databricks environment, project architecture, data workloads and business objectives. Programs can include hands-on notebooks, pipeline exercises, SQL scenarios, engineering assignments and implementation discussions.
Whether your organization is adopting Databricks, strengthening an existing lakehouse environment, improving data engineering practices or developing internal Databricks capabilities, the program can be structured around practical team requirements.
The program can cover Databricks fundamentals, lakehouse architecture, Apache Spark, Delta Lake, Lakeflow, Databricks SQL, Unity Catalog, data pipelines, governance and production data workflows.
Corporate Databricks training can support data engineers, data analysts, developers, architects, analytics professionals and technology teams working with modern data platforms.
Yes. The curriculum can be customized around your team's roles, experience, Databricks environment, project requirements, data platform architecture and business objectives.
The training can include Apache Spark DataFrames, transformations, joins, aggregations, scalable processing, Delta Lake tables, transactional data processing, schema evolution and incremental data engineering workflows.
The program can include Unity Catalog concepts such as catalog and schema organization, access control, auditing, discovery and data lineage for governed data workflows.
Discuss your team's roles, project requirements, preferred delivery model and Databricks skill objectives with our corporate training team.